The only agent that thinks for itself

Autonomous Monitoring with self-learning AI built-in, operating independently across your entire stack.

Unlimited Metrics & Logs
Machine learning & MCP
5% CPU, 150MB RAM
3GB disk, >1 year retention
800+ integrations, zero config
Dashboards, alerts out of the box
> Discover Netdata Agents

Centralized metrics streaming and storage

Aggregate metrics from multiple agents into centralized Parent nodes for unified monitoring across your infrastructure.

Stream from unlimited agents
Long-term data retention
High availability clustering
Data replication & backup
Scalable architecture
Enterprise-grade security
> Learn about Parents

Fully managed cloud platform

Access your monitoring data from anywhere with our SaaS platform. No infrastructure to manage, automatic updates, and global availability.

Zero infrastructure management
99.9% uptime SLA
Global data centers
Automatic updates & patches
Enterprise SSO & RBAC
SOC2 & ISO certified
> Explore Netdata Cloud

Deploy Netdata Cloud in your infrastructure

Run the full Netdata Cloud platform on-premises for complete data sovereignty and compliance with your security policies.

Complete data sovereignty
Air-gapped deployment
Custom compliance controls
Private network integration
Dedicated support team
Kubernetes & Docker support
> Learn about Cloud On-Premises

Powerful, intuitive monitoring interface

Modern, responsive UI built for real-time troubleshooting with customizable dashboards and advanced visualization capabilities.

Real-time chart updates
Customizable dashboards
Dark & light themes
Advanced filtering & search
Responsive on all devices
Collaboration features
> Explore Netdata UI

Monitor on the go

Native iOS and Android apps bring full monitoring capabilities to your mobile device with real-time alerts and notifications.

iOS & Android apps
Push notifications
Touch-optimized interface
Offline data access
Biometric authentication
Widget support
> Download apps

The future of infrastructure observability

See our strategic direction across AI-native observability, full-stack signals, operational intelligence, and enterprise platform maturity.

AI-native observability
Full-stack signal coverage
Operational intelligence
Enterprise platform maturity
Agent releases every 6 weeks
Cloud continuous delivery
> Explore Product Roadmap

Best energy efficiency

True real-time per-second

100% automated zero config

Centralized observability

Multi-year retention

High availability built-in

Zero maintenance

Always up-to-date

Enterprise security

Complete data control

Air-gap ready

Compliance certified

Millisecond responsiveness

Infinite zoom & pan

Works on any device

Native performance

Instant alerts

Monitor anywhere

AI-native observability

Continuous delivery

Open source foundation

80% Faster Incident Resolution

AI-powered troubleshooting from detection, to root cause and blast radius identification, to reporting.

True Real-Time and Simple, even at Scale

Linearly and infinitely scalable full-stack observability, that can be deployed even mid-crisis.

90% Cost Reduction, Full Fidelity

Instead of centralizing the data, Netdata distributes the code, eliminating pipelines and complexity.

See and Map Your Entire Network

Live topology, flow analytics, and SNMP device and trap monitoring — unified with your full-stack observability.

Control Without Surrender

SOC 2 Type 2 certified with every metric kept on your infrastructure.

Integrations

800+ collectors and notification channels, auto-discovered and ready out of the box.

800+ data collectors
Auto-discovery & zero config
Cloud, infra, app protocols
Notifications out of the box
> Explore integrations
Real Results
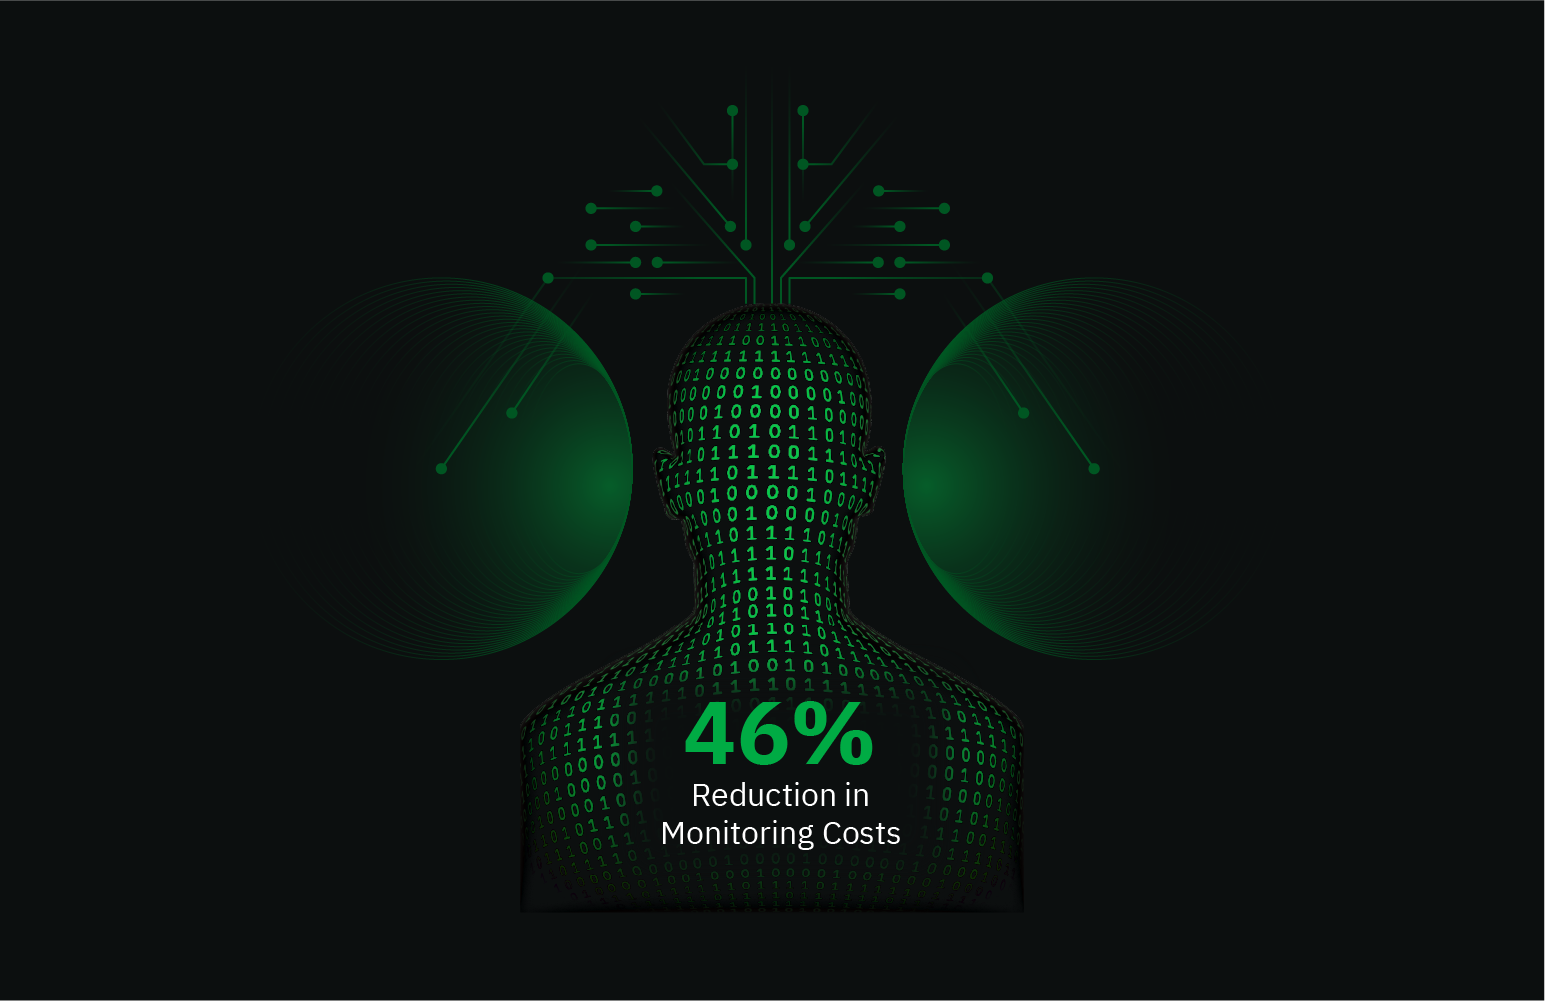
46% Cost Reduction

Reduced monitoring costs by 46% while cutting staff overhead by 67%.

— Leonardo Antunez, Codyas

Zero Pipeline

No data shipping. No central storage costs. Query at the edge.

From Our Users
"Out-of-the-Box"

So many out-of-the-box features! I mostly don't have to develop anything.

— Simon Beginn, LANCOM Systems

No Query Language

Point-and-click troubleshooting. No PromQL, no LogQL, no learning curve.

Enterprise Ready
67% Less Staff, 46% Cost Cut

Enterprise efficiency without enterprise complexity—real ROI from day one.

— Leonardo Antunez, Codyas

SOC 2 Type 2 Certified

Zero data egress. Only metadata reaches the cloud. Your metrics stay on your infrastructure.

Full Coverage
800+ Collectors

Auto-discovered and configured. No manual setup required.

Any Notification Channel

Slack, PagerDuty, Teams, email, webhooks—all built-in.

Built for the People Who Get Paged

Because 3am alerts deserve instant answers, not hour-long hunts.

Every Industry Has Rules. We Master Them.

See how healthcare, finance, and government teams cut monitoring costs 90% while staying audit-ready.

Monitor Any Technology. Configure Nothing.

Install the agent. It already knows your stack.
From Our Users
"A Rare Unicorn"

Netdata gives more than you invest in it. A rare unicorn that obeys the Pareto rule.

— Eduard Porquet Mateu, TMB Barcelona

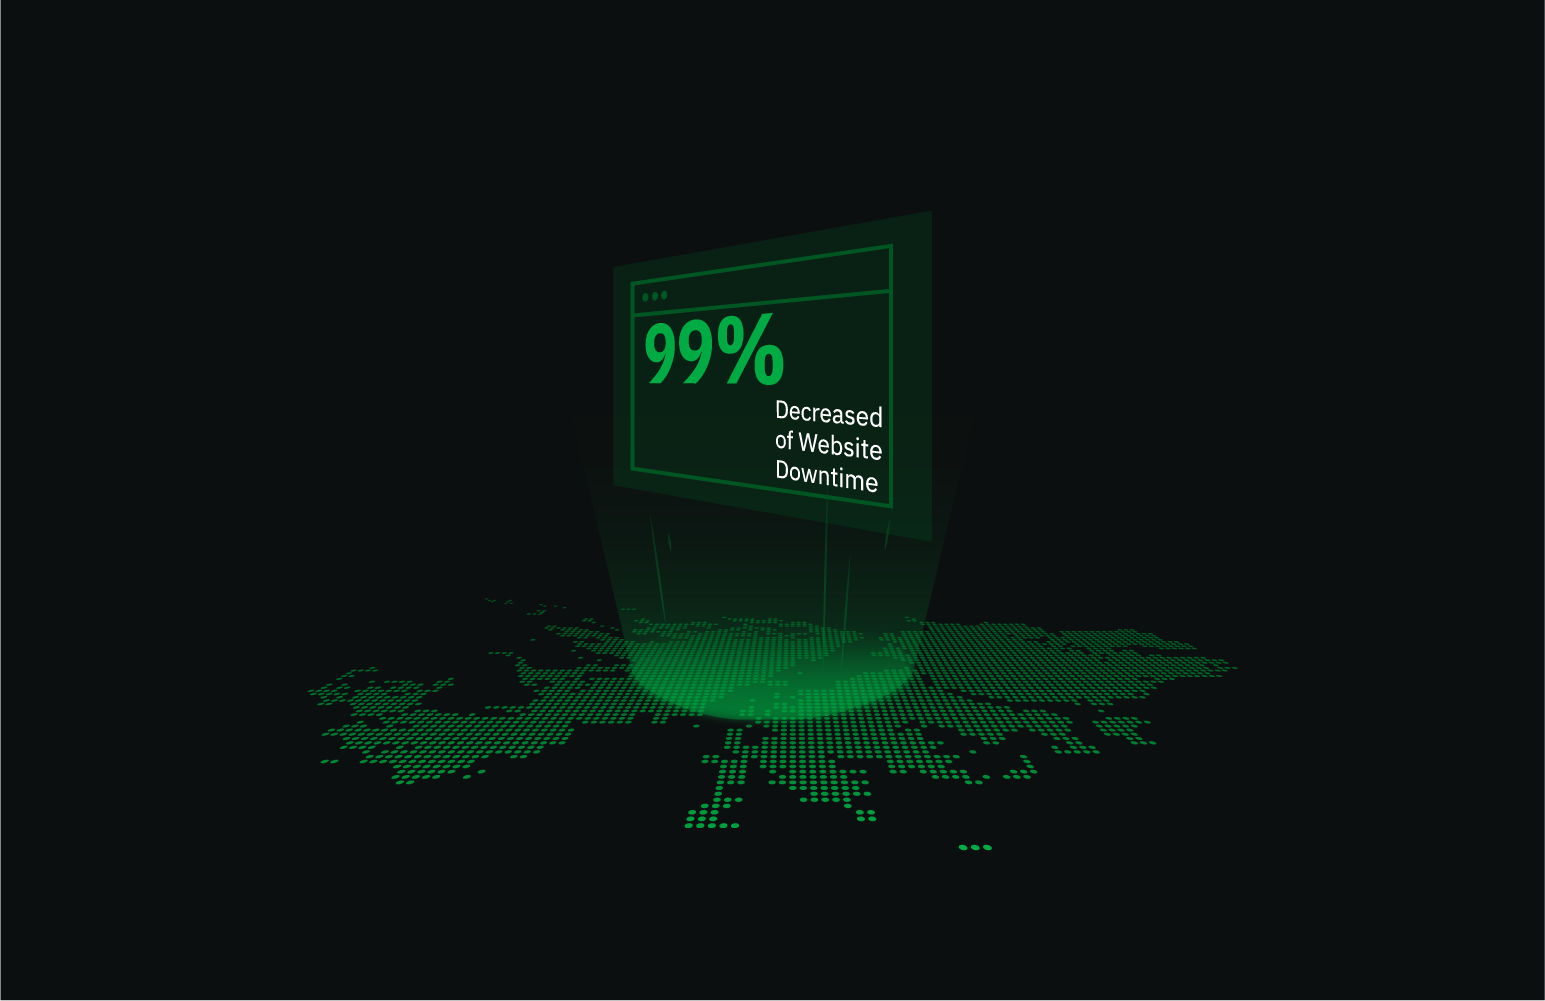
99% Downtime Reduction

Reduced website downtime by 99% and cloud bill by 30% using Netdata alerts.

— Falkland Islands Government

Real Savings
30% Cloud Cost Reduction

Optimized resource allocation based on Netdata alerts cut cloud spending by 30%.

— Falkland Islands Government

46% Cost Cut

Reduced monitoring staff by 67% while cutting operational costs by 46%.

— Codyas

Real Coverage
"Plugin for Everything"

Netdata has agent capacity or a plugin for everything, including Windows and Kubernetes.

— Eduard Porquet Mateu, TMB Barcelona

"Out-of-the-Box"

So many out-of-the-box features! I mostly don't have to develop anything.

— Simon Beginn, LANCOM Systems

Real Speed
Troubleshooting in 30 Seconds

From 2-3 minutes to 30 seconds—instant visibility into any node issue.

— Matthew Artist, Nodecraft

20% Downtime Reduction

20% less downtime and 40% budget optimization from out-of-the-box monitoring.

— Simon Beginn, LANCOM Systems

Pay per Node. Unlimited Everything Else.

One price per node. Unlimited metrics, logs, users, and retention. No per-GB surprises.

Free tier—forever
No metric limits or caps
Retention you control
Cancel anytime
> See pricing plans

What's Your Monitoring Really Costing You?

Most teams overpay by 40-60%. Let's find out why.

Expose hidden metric charges
Calculate tool consolidation
Customers report 30-67% savings
Results in under 60 seconds
> See what you're really paying

Your Infrastructure Is Unique. Let's Talk.

Because monitoring 10 nodes is different from monitoring 10,000.

On-prem & air-gapped deployment
Volume pricing & agreements
Architecture review for your scale
Compliance & security support
> Start a conversation

Monitoring That Sells Itself

Deploy in minutes. Impress clients in hours. Earn recurring revenue for years.

30-second live demos close deals
Zero config = zero support burden
Competitive margins & deal protection
Response in 48 hours
> Apply to partner

Per-Second Metrics at Homelab Prices

Same engine, same dashboards, same ML. Just priced for tinkerers.

Community: Free forever · 5 nodes · non-commercial
Homelab: $90/yr · unlimited nodes · fair usage
> Get the Homelab Plan

$1,000 Per Referral. Unlimited Referrals.

Your colleagues get 10% off. You get 10% commission. Everyone wins.

10% of subscriptions, up to $1,000 each
Track earnings inside Netdata Cloud
PayPal/Venmo payouts in 3-4 weeks
No caps, no complexity
> Get your referral link
Cost Proof
40% Budget Optimization

"Netdata's significant positive impact" — LANCOM Systems

Calculate Your Savings

Compare vs Datadog, Grafana, Dynatrace

Savings Proof
46% Cost Reduction

"Cut costs by 46%, staff by 67%" — Codyas

30% Cloud Bill Savings

"Reduced cloud bill by 30%" — Falkland Islands Gov

Enterprise Proof
"Better Than Combined Alternatives"

"Better observability with Netdata than combining other tools." — TMB Barcelona

Real Engineers, <24h Response

DPA, SLAs, on-prem, volume pricing

Why Partners Win
Demo Live Infrastructure

One command, 30 seconds, real data—no sandbox needed

Zero Tickets, High Margins

Auto-config + per-node pricing = predictable profit

Homelab Ready
Free Video Course

8-episode Netdata tutorial by LearnLinux.tv

76k+ GitHub Stars

3rd most starred monitoring project

Worth Recommending
Product That Delivers

Customers report 40-67% cost cuts, 99% downtime reduction

Zero Risk to Your Rep

Free tier lets them try before they buy

AI Support Assistant, Available 24/7

Nedi has access to all official documentation, source code, and resources. Ask any question about Netdata—responds in your language.

Deployment & configuration
Troubleshooting & sizing
Alerts & notifications
Evidence-based answers
> Ask Nedi now

Never Fight Fires Alone

Docs, community, and expert help—pick your path to resolution.

Learn.netdata.cloud docs
Discord, Forums, GitHub
Premium support available
> Get answers now

60 Seconds to First Dashboard

One command to install. Zero config. 850+ integrations documented.

Linux, Windows, K8s, Docker
Auto-discovers your stack
> Read our documentation

76,000+ Engineers Strong

615+ contributors. 1.5M daily downloads. One mission: simplify observability.

Per-Second. 90% Cheaper. Data Stays Home.

Side-by-side comparisons: costs, real-time granularity, and data sovereignty for every major tool.

See why teams switch from Datadog, Prometheus, Grafana, and more.

> Browse all comparisons
Edge-Native Observability, Born Open Source
Per-second visibility, ML on every metric, and data that never leaves your infrastructure.
Founded in 2016
615+ contributors worldwide
Remote-first, engineering-driven
Open source first
> Read our story
Promises We Publish—and Prove
12 principles backed by open code, independent validation, and measurable outcomes.
Open source, peer-reviewed
Zero config, instant value
Data sovereignty by design
Aligned pricing, no surprises
> See all 12 principles
Edge-Native, AI-Ready, 100% Open
76k+ stars. Full ML, AI, and automation—GPLv3+, not premium add-ons.
76,000+ GitHub stars
GPLv3+ licensed forever
ML on every metric, included
Zero vendor lock-in
> Explore our open source
Build Real-Time Observability for the World
Remote-first team shipping per-second monitoring with ML on every metric.
Remote-first, fully distributed
Open source (76k+ stars)
Challenging technical problems
Your code on millions of systems
> See open roles
Meet the Team Behind Netdata
Conferences, meetups, and tradeshows where you can see Netdata in action and talk to the engineers who build it.
Live demos and deep dives
Book 1-on-1 meetings
Talks and panel sessions
Event recaps and photos
> See all events
Talk to a Netdata Human in <24 Hours
Sales, partnerships, press, or professional services—real engineers, fast answers.
Discuss your observability needs
Pricing and volume discounts
Partnership opportunities
Media and press inquiries
> Book a conversation
Your Data. Your Rules.
On-prem data, cloud control plane, transparent terms.
Trust & Scale
76,000+ GitHub Stars

One of the most popular open-source monitoring projects

SOC 2 Type 2 Certified

Enterprise-grade security and compliance

Data Sovereignty

Your metrics stay on your infrastructure

Validated
University of Amsterdam

"Most energy-efficient monitoring solution" — ICSOC 2023, peer-reviewed

ADASTEC (Autonomous Driving)

"Doesn't miss alerts—mission-critical trust for safety software"

Community Stats
615+ Contributors

Global community improving monitoring for everyone

1.5M+ Downloads/Day

Trusted by teams worldwide

GPLv3+ Licensed

Free forever, fully open source agent

Why Join?
Remote-First

Work from anywhere, async-friendly culture

Impact at Scale

Your work helps millions of systems

Reliability

Designing Error Budget Policies For SLOs At Scale

A practical framework for turning reliability targets into a quantifiable resource that drives engineering decisions
by Netdata Team · September 4, 2025

In every engineering organization, there’s a constant, fundamental tension: the push to ship new features versus the need to maintain a stable, reliable service. Move too fast, and you risk outages that erode user trust. Move too slowly, and you risk being outpaced by the competition. For years, this balancing act was managed by intuition, late-night heroics, and tense priority meetings. Site Reliability Engineering (SRE) offers a better way: the error budget.

An error budget is not about “budgeting downtime.” It’s a data-driven framework that reframes reliability as a product feature. It turns the vague goal of “making the system stable” into a quantifiable resource that both product and engineering teams can manage. By designing a robust error budget policy, you create a pact that allows for maximum innovation velocity while guaranteeing a specific reliability target for your users.

The Language of Reliability: SLIs, SLOs, and Error Budgets

Before you can budget for errors, you need a common language to talk about reliability. This language is built on three core concepts.

  • Service Level Indicator (SLI): An SLI is a quantitative measure of some aspect of your service. It must be something you can actually count. The best SLIs are structured as a ratio of good events to total valid events.

    • Availability SLI: (Number of successful requests) / (Total valid requests)
    • Latency SLI: (Number of requests faster than a threshold) / (Total valid requests)
  • Service Level Objective (SLO): An SLO is the target value for your SLI over a specific period. This is the goal you are committing to. It is a precise statement about the desired level of reliability.

    • Example SLO: “99.9% of homepage requests over a rolling 28-day window will be successful.”
  • Error Budget: The error budget is simply 100% - SLO. It represents the acceptable level of unreliability. It is not a goal to be spent, but a limit on how much unreliability your users will tolerate before you must take corrective action.

    • Example Budget: For a 99.9% SLO, your error budget is 0.1%. If you receive 10 million requests in 28 days, your budget is 10,000 errors.

This framework moves the conversation away from an impossible goal of 100% uptime and toward a realistic, user-centric availability target.

Calculating Your First Error Budget: A Step-by-Step Guide

Creating your first error budget doesn’t have to be perfect; it just has to be a starting point. The process is iterative.

Step 1: Choose Your SLIs (What to Measure)

Start with what your users care about most. Don’t measure everything; pick a handful of key indicators that represent the core user experience.

  • For user-facing systems: Availability and latency are the universal starting points. Can users access the service? Is it fast enough?
  • For data pipelines: Freshness and correctness are key. Is the data up-to-date? Is it accurate?
  • For storage systems: Durability and availability are paramount. Is my data safe? Can I access it when I need to?

When defining these, think in terms of distributions, not averages. An average latency can hide a terrible user experience for a small but important subset of your users. Use percentiles (e.g., 90th, 95th, 99th) to understand the experience of the typical user and the long tail.

Step 2: Set Your SLOs (What to Target)

Choosing the right target is a negotiation between product, engineering, and what’s technically feasible. However, there are some guiding principles.

  • 100% is the Wrong Target: The single biggest source of outages is change. A 100% SLO would mean you can never deploy new features, apply security patches, or scale your infrastructure. Furthermore, even if your service is 100% available, dependencies in the user’s path (their ISP, local network, etc.) mean they will never experience 100% reliability.
  • Don’t Just Use Current Performance: While it’s tempting to look at your historical performance (e.g., “we were 99.95% available last month”) and set that as the SLO, this can be a trap. You might lock yourself into a target that requires heroic effort to maintain. Use historical data as a starting point for discussion, not the final answer.
  • Keep it Simple: An SLO should be easy to explain and understand. “99.9% of successful logins in under 500ms” is clear. A complex, multi-variable SLO is hard to track and even harder to act upon.

Step 3: Do the Math

Once you have your SLO, the budget calculation is straightforward. If your availability SLO is 99.9% over a 28-day period, your error budget is 0.1%. Every failed request during that period consumes a portion of that budget. This simple calculation transforms an abstract percentage into a concrete number of “unhappy user events” you can afford.

The Heart of Governance: The Error Budget Policy

Calculating the budget is easy. Agreeing on what to do with it is hard. An error budget policy is a formal document, a pre-negotiated contract between stakeholders (SRE, development, product) that defines the rules of engagement. Without a policy, your SLO is just a number on a dashboard, not a tool for decision-making.

A strong error budget policy must contain:

  1. Clear Triggers: When is the policy invoked? This isn’t just when the budget hits zero. A key concept is the burn rate alert. A fast burn alert might trigger if you consume 10% of your monthly budget in under 24 hours. This is an early warning system that allows for course correction.
  2. Defined Consequences: What happens when a trigger is fired? This must be explicit and agreed upon in advance.
    • “Yellow Alert” (Fast Burn): A team meeting is called to analyze the cause. Low-risk feature deployments may continue, but high-risk changes are paused.
    • “Red Alert” (Budget Exhausted): All feature development is halted. The development team’s top priority shifts to reliability work—fixing bugs, paying down technical debt, or improving test coverage. New releases are frozen until enough budget is accrued for the next release.
  3. Ownership and Accountability: The policy must state who is responsible for declaring a freeze (e.g., the SRE team lead, the product owner) and who is responsible for executing the reliability work (the development team).
  4. Escalation Path: What happens if there’s a disagreement? There must be a clear path for escalating the decision, typically to a director or VP of Engineering who can make the final call based on broader business context.

Getting buy-in for this policy is the ultimate test of your SLOs. If developers feel the consequences are too punitive for the given target, the SLO may be too strict. If the product owner feels the service will be unacceptably bad before a freeze is triggered, the SLO is too loose. This negotiation is what aligns the entire organization around a shared definition of “good enough.”

Tracking and Enforcement at Scale

With a policy in place, you need tooling to make it visible and actionable.

  • SLO Dashboards: You cannot manage what you do not measure. A dedicated SLO dashboard is essential. It should visualize, at a minimum:
    • The current SLI value.
    • The SLO target.
    • The remaining error budget for the period.
    • A burndown chart showing the rate of budget consumption over time. This makes the burn rate intuitive and visible to everyone.
  • Burn Rate Alerting: Your SLO monitoring system must be configured with multi-window, multi-burn-rate alerts. These alerts are the automated triggers for your policy. For example:
    • High Priority Alert: “Alert if we are on track to consume our 28-day error budget in the next 3 days.” This requires immediate attention.
    • Low Priority Ticket: “Create a ticket if we have consumed 2% of our quarterly budget in the last 6 hours.” This flags an issue for the next planning meeting.
  • Governance and Review Cadence: SLOs are not static. The business changes, user expectations change, and your systems evolve. Establish a quarterly SRE governance meeting to review SLO performance.
    • Did our SLOs accurately reflect customer impact?
    • Were our burn rate alerts effective, or were they too noisy/too slow?
    • Do we need to adjust our SLO targets for the next quarter?
    • Did we spend our error budget on valuable experiments or on preventable failures?

An error budget transforms reliability from an emotional, often contentious topic into a rational, data-driven engineering discipline. It creates a virtuous cycle: it provides developers with the autonomy to innovate quickly when the service is healthy and provides SREs with the clear mandate to put the brakes on when reliability dips below the user-agreed target. It is the most powerful tool for building services that are not just reliable, but reliably innovative.

To effectively manage an error budget, you need high-resolution, real-time data for your SLIs. Latency or gaps in your monitoring data can lead to inaccurate budget calculations and missed alerts. Netdata’s per-second monitoring provides the granularity needed to build precise SLOs and catch fast-burning budget consumption before it threatens your reliability targets.