The only agent that thinks for itself

Autonomous Monitoring with self-learning AI built-in, operating independently across your entire stack.

Unlimited Metrics & Logs
Machine learning & MCP
5% CPU, 150MB RAM
3GB disk, >1 year retention
800+ integrations, zero config
Dashboards, alerts out of the box
> Discover Netdata Agents

Centralized metrics streaming and storage

Aggregate metrics from multiple agents into centralized Parent nodes for unified monitoring across your infrastructure.

Stream from unlimited agents
Long-term data retention
High availability clustering
Data replication & backup
Scalable architecture
Enterprise-grade security
> Learn about Parents

Fully managed cloud platform

Access your monitoring data from anywhere with our SaaS platform. No infrastructure to manage, automatic updates, and global availability.

Zero infrastructure management
99.9% uptime SLA
Global data centers
Automatic updates & patches
Enterprise SSO & RBAC
SOC2 & ISO certified
> Explore Netdata Cloud

Deploy Netdata Cloud in your infrastructure

Run the full Netdata Cloud platform on-premises for complete data sovereignty and compliance with your security policies.

Complete data sovereignty
Air-gapped deployment
Custom compliance controls
Private network integration
Dedicated support team
Kubernetes & Docker support
> Learn about Cloud On-Premises

Powerful, intuitive monitoring interface

Modern, responsive UI built for real-time troubleshooting with customizable dashboards and advanced visualization capabilities.

Real-time chart updates
Customizable dashboards
Dark & light themes
Advanced filtering & search
Responsive on all devices
Collaboration features
> Explore Netdata UI

Monitor on the go

Native iOS and Android apps bring full monitoring capabilities to your mobile device with real-time alerts and notifications.

iOS & Android apps
Push notifications
Touch-optimized interface
Offline data access
Biometric authentication
Widget support
> Download apps

The future of infrastructure observability

See our strategic direction across AI-native observability, full-stack signals, operational intelligence, and enterprise platform maturity.

AI-native observability
Full-stack signal coverage
Operational intelligence
Enterprise platform maturity
Agent releases every 6 weeks
Cloud continuous delivery
> Explore Product Roadmap

Best energy efficiency

True real-time per-second

100% automated zero config

Centralized observability

Multi-year retention

High availability built-in

Zero maintenance

Always up-to-date

Enterprise security

Complete data control

Air-gap ready

Compliance certified

Millisecond responsiveness

Infinite zoom & pan

Works on any device

Native performance

Instant alerts

Monitor anywhere

AI-native observability

Continuous delivery

Open source foundation

80% Faster Incident Resolution

AI-powered troubleshooting from detection, to root cause and blast radius identification, to reporting.

True Real-Time and Simple, even at Scale

Linearly and infinitely scalable full-stack observability, that can be deployed even mid-crisis.

90% Cost Reduction, Full Fidelity

Instead of centralizing the data, Netdata distributes the code, eliminating pipelines and complexity.

See and Map Your Entire Network

Live topology, flow analytics, and SNMP device and trap monitoring — unified with your full-stack observability.

Control Without Surrender

SOC 2 Type 2 certified with every metric kept on your infrastructure.

Integrations

800+ collectors and notification channels, auto-discovered and ready out of the box.

800+ data collectors
Auto-discovery & zero config
Cloud, infra, app protocols
Notifications out of the box
> Explore integrations
Real Results
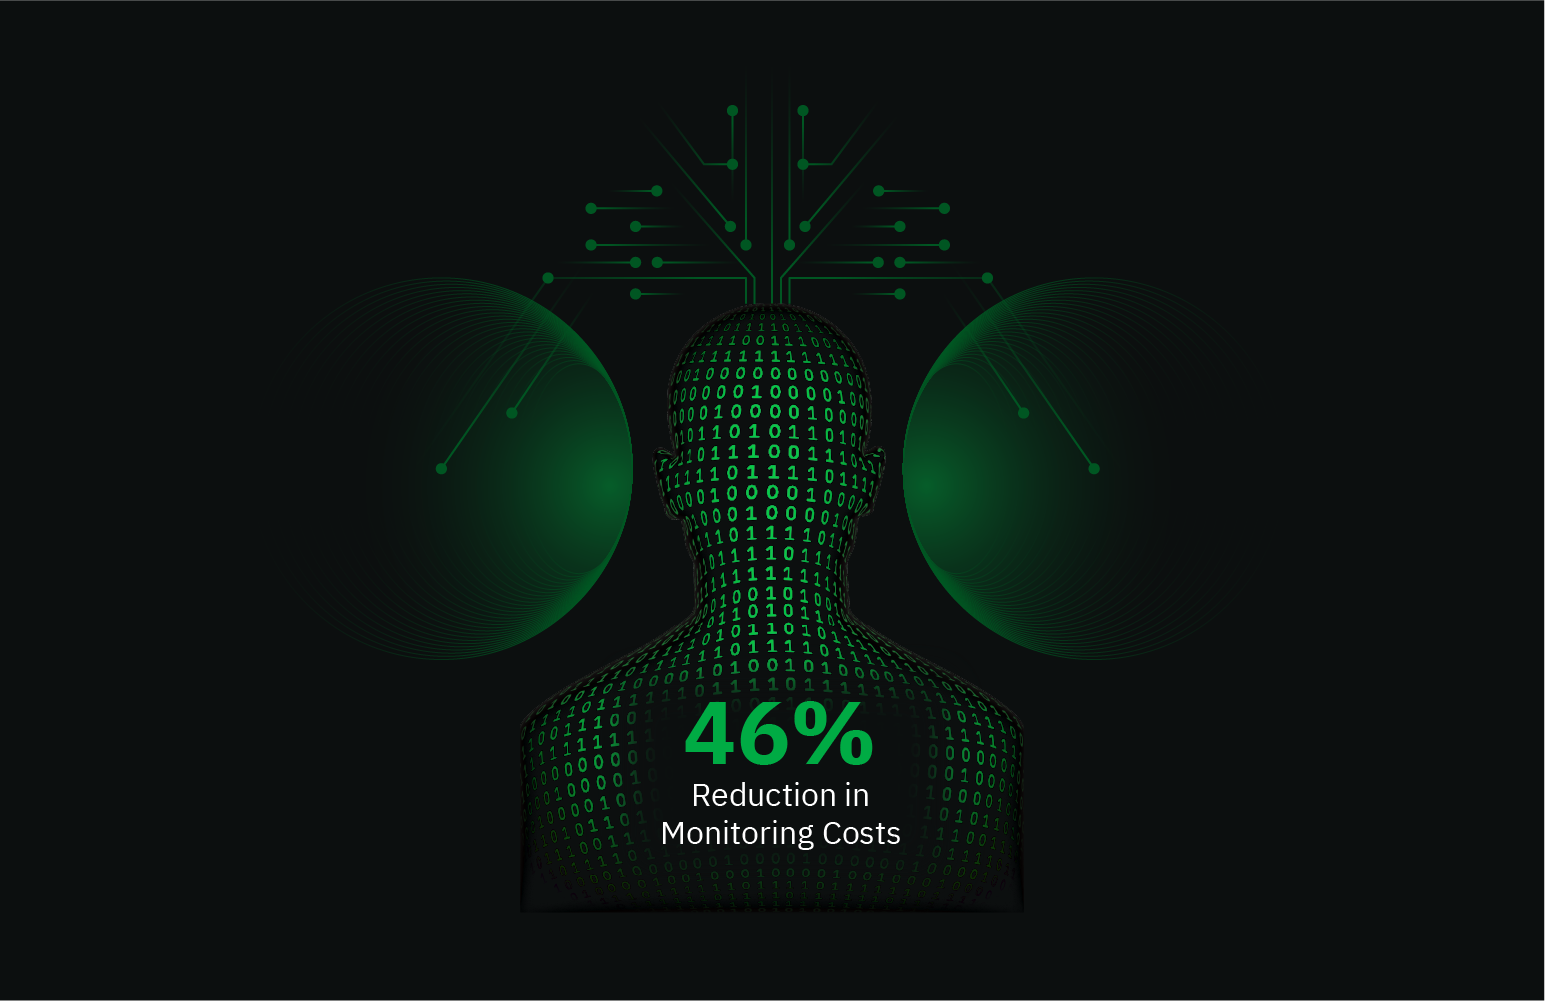
46% Cost Reduction

Reduced monitoring costs by 46% while cutting staff overhead by 67%.

— Leonardo Antunez, Codyas

Zero Pipeline

No data shipping. No central storage costs. Query at the edge.

From Our Users
"Out-of-the-Box"

So many out-of-the-box features! I mostly don't have to develop anything.

— Simon Beginn, LANCOM Systems

No Query Language

Point-and-click troubleshooting. No PromQL, no LogQL, no learning curve.

Enterprise Ready
67% Less Staff, 46% Cost Cut

Enterprise efficiency without enterprise complexity—real ROI from day one.

— Leonardo Antunez, Codyas

SOC 2 Type 2 Certified

Zero data egress. Only metadata reaches the cloud. Your metrics stay on your infrastructure.

Full Coverage
800+ Collectors

Auto-discovered and configured. No manual setup required.

Any Notification Channel

Slack, PagerDuty, Teams, email, webhooks—all built-in.

Built for the People Who Get Paged

Because 3am alerts deserve instant answers, not hour-long hunts.

Every Industry Has Rules. We Master Them.

See how healthcare, finance, and government teams cut monitoring costs 90% while staying audit-ready.

Monitor Any Technology. Configure Nothing.

Install the agent. It already knows your stack.
From Our Users
"A Rare Unicorn"

Netdata gives more than you invest in it. A rare unicorn that obeys the Pareto rule.

— Eduard Porquet Mateu, TMB Barcelona

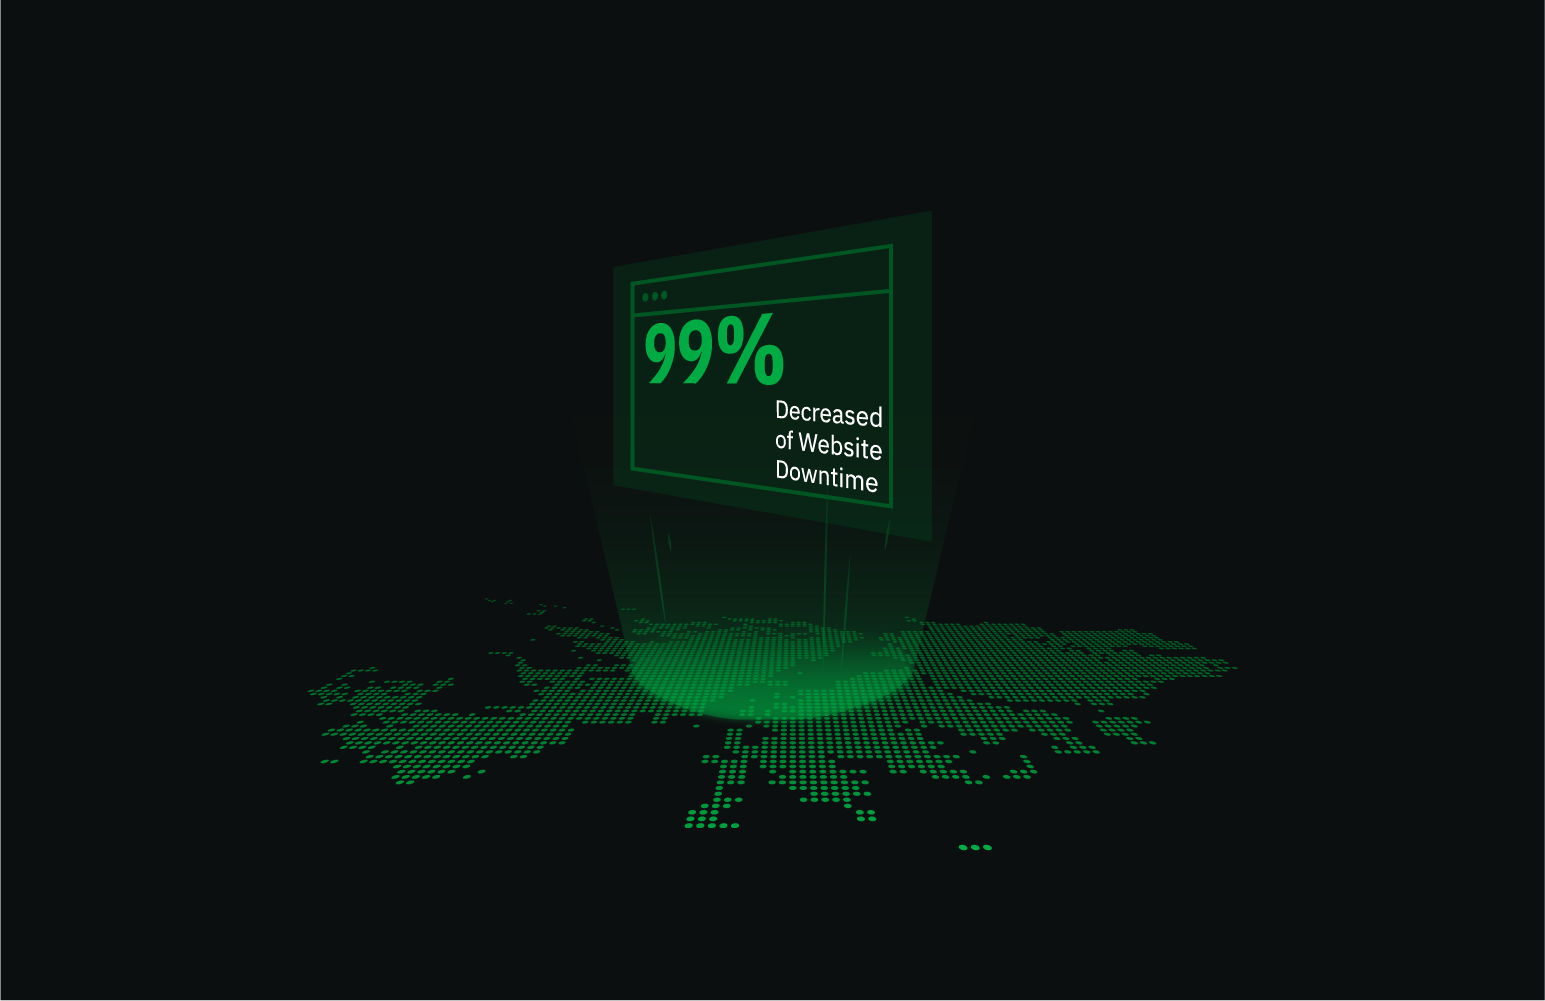
99% Downtime Reduction

Reduced website downtime by 99% and cloud bill by 30% using Netdata alerts.

— Falkland Islands Government

Real Savings
30% Cloud Cost Reduction

Optimized resource allocation based on Netdata alerts cut cloud spending by 30%.

— Falkland Islands Government

46% Cost Cut

Reduced monitoring staff by 67% while cutting operational costs by 46%.

— Codyas

Real Coverage
"Plugin for Everything"

Netdata has agent capacity or a plugin for everything, including Windows and Kubernetes.

— Eduard Porquet Mateu, TMB Barcelona

"Out-of-the-Box"

So many out-of-the-box features! I mostly don't have to develop anything.

— Simon Beginn, LANCOM Systems

Real Speed
Troubleshooting in 30 Seconds

From 2-3 minutes to 30 seconds—instant visibility into any node issue.

— Matthew Artist, Nodecraft

20% Downtime Reduction

20% less downtime and 40% budget optimization from out-of-the-box monitoring.

— Simon Beginn, LANCOM Systems

Pay per Node. Unlimited Everything Else.

One price per node. Unlimited metrics, logs, users, and retention. No per-GB surprises.

Free tier—forever
No metric limits or caps
Retention you control
Cancel anytime
> See pricing plans

What's Your Monitoring Really Costing You?

Most teams overpay by 40-60%. Let's find out why.

Expose hidden metric charges
Calculate tool consolidation
Customers report 30-67% savings
Results in under 60 seconds
> See what you're really paying

Your Infrastructure Is Unique. Let's Talk.

Because monitoring 10 nodes is different from monitoring 10,000.

On-prem & air-gapped deployment
Volume pricing & agreements
Architecture review for your scale
Compliance & security support
> Start a conversation

Monitoring That Sells Itself

Deploy in minutes. Impress clients in hours. Earn recurring revenue for years.

30-second live demos close deals
Zero config = zero support burden
Competitive margins & deal protection
Response in 48 hours
> Apply to partner

Per-Second Metrics at Homelab Prices

Same engine, same dashboards, same ML. Just priced for tinkerers.

Community: Free forever · 5 nodes · non-commercial
Homelab: $90/yr · unlimited nodes · fair usage
> Get the Homelab Plan

$1,000 Per Referral. Unlimited Referrals.

Your colleagues get 10% off. You get 10% commission. Everyone wins.

10% of subscriptions, up to $1,000 each
Track earnings inside Netdata Cloud
PayPal/Venmo payouts in 3-4 weeks
No caps, no complexity
> Get your referral link
Cost Proof
40% Budget Optimization

"Netdata's significant positive impact" — LANCOM Systems

Calculate Your Savings

Compare vs Datadog, Grafana, Dynatrace

Savings Proof
46% Cost Reduction

"Cut costs by 46%, staff by 67%" — Codyas

30% Cloud Bill Savings

"Reduced cloud bill by 30%" — Falkland Islands Gov

Enterprise Proof
"Better Than Combined Alternatives"

"Better observability with Netdata than combining other tools." — TMB Barcelona

Real Engineers, <24h Response

DPA, SLAs, on-prem, volume pricing

Why Partners Win
Demo Live Infrastructure

One command, 30 seconds, real data—no sandbox needed

Zero Tickets, High Margins

Auto-config + per-node pricing = predictable profit

Homelab Ready
Free Video Course

8-episode Netdata tutorial by LearnLinux.tv

76k+ GitHub Stars

3rd most starred monitoring project

Worth Recommending
Product That Delivers

Customers report 40-67% cost cuts, 99% downtime reduction

Zero Risk to Your Rep

Free tier lets them try before they buy

AI Support Assistant, Available 24/7

Nedi has access to all official documentation, source code, and resources. Ask any question about Netdata—responds in your language.

Deployment & configuration
Troubleshooting & sizing
Alerts & notifications
Evidence-based answers
> Ask Nedi now

Never Fight Fires Alone

Docs, community, and expert help—pick your path to resolution.

Learn.netdata.cloud docs
Discord, Forums, GitHub
Premium support available
> Get answers now

60 Seconds to First Dashboard

One command to install. Zero config. 850+ integrations documented.

Linux, Windows, K8s, Docker
Auto-discovers your stack
> Read our documentation

76,000+ Engineers Strong

615+ contributors. 1.5M daily downloads. One mission: simplify observability.

Per-Second. 90% Cheaper. Data Stays Home.

Side-by-side comparisons: costs, real-time granularity, and data sovereignty for every major tool.

See why teams switch from Datadog, Prometheus, Grafana, and more.

> Browse all comparisons
Edge-Native Observability, Born Open Source
Per-second visibility, ML on every metric, and data that never leaves your infrastructure.
Founded in 2016
615+ contributors worldwide
Remote-first, engineering-driven
Open source first
> Read our story
Promises We Publish—and Prove
12 principles backed by open code, independent validation, and measurable outcomes.
Open source, peer-reviewed
Zero config, instant value
Data sovereignty by design
Aligned pricing, no surprises
> See all 12 principles
Edge-Native, AI-Ready, 100% Open
76k+ stars. Full ML, AI, and automation—GPLv3+, not premium add-ons.
76,000+ GitHub stars
GPLv3+ licensed forever
ML on every metric, included
Zero vendor lock-in
> Explore our open source
Build Real-Time Observability for the World
Remote-first team shipping per-second monitoring with ML on every metric.
Remote-first, fully distributed
Open source (76k+ stars)
Challenging technical problems
Your code on millions of systems
> See open roles
Meet the Team Behind Netdata
Conferences, meetups, and tradeshows where you can see Netdata in action and talk to the engineers who build it.
Live demos and deep dives
Book 1-on-1 meetings
Talks and panel sessions
Event recaps and photos
> See all events
Talk to a Netdata Human in <24 Hours
Sales, partnerships, press, or professional services—real engineers, fast answers.
Discuss your observability needs
Pricing and volume discounts
Partnership opportunities
Media and press inquiries
> Book a conversation
Your Data. Your Rules.
On-prem data, cloud control plane, transparent terms.
Trust & Scale
76,000+ GitHub Stars

One of the most popular open-source monitoring projects

SOC 2 Type 2 Certified

Enterprise-grade security and compliance

Data Sovereignty

Your metrics stay on your infrastructure

Validated
University of Amsterdam

"Most energy-efficient monitoring solution" — ICSOC 2023, peer-reviewed

ADASTEC (Autonomous Driving)

"Doesn't miss alerts—mission-critical trust for safety software"

Community Stats
615+ Contributors

Global community improving monitoring for everyone

1.5M+ Downloads/Day

Trusted by teams worldwide

GPLv3+ Licensed

Free forever, fully open source agent

Why Join?
Remote-First

Work from anywhere, async-friendly culture

Impact at Scale

Your work helps millions of systems

Observability

What Is Structured Logging And How To Utilize It Effectively

Transform your logs from plain text into powerful- queryable data for enhanced observability and troubleshooting- understanding log structure is key.
by Netdata Team · May 27, 2025

Dealing with gigabytes of plain text log files can feel like searching for a needle in a haystack, especially when critical systems are down. Unstructured logs make it incredibly difficult to quickly pinpoint issues, correlate events, or gain meaningful insights from the vast amount of data your applications generate. If you’ve ever struggled to filter logs by a specific customer ID or trace a transaction across multiple services, you understand the pain. This is precisely where structured logging steps in, transforming your log data from a chaotic stream of text into a valuable, queryable asset.

Understanding and implementing structured logs is no longer a niche practice; it’s a fundamental component of modern software development and operations. It empowers developers, DevOps engineers, and SREs to diagnose problems faster, monitor system health more effectively, and even derive business intelligence from operational data.

What is Structured Logging?

Structured logging is the practice of recording application and system events in a consistent, predefined format, typically using key-value pairs. Instead of writing log messages as free-form text strings, each log entry becomes a self-contained data object. This makes logs easily parsable by machines, enabling efficient searching, filtering, and analysis.

The most common format for structured logs is JSON, due to its widespread support and human readability. Other formats like XML exist but are less prevalent in modern logging stacks.

Consider a traditional, unstructured log entry: a simple text line stating a user login failed with a reason. While a human can understand this, a machine would need complex parsing rules. Now, imagine its structured equivalent: a JSON object with distinct fields for “timestamp,” “level,” “message,” “event_type,” “user_id,” “reason,” and “source_ip.”

This log structure is immediately more useful. You can easily query for all “USER_LOGIN_FAIL” events, or all events related to a specific “user_id”, or all debug messages from a particular IP address. This ability to treat logs as data sets is the core power of structured logging.

Why Is Structured Logging Essential?

Traditional plain text logs present several challenges. They are often inconsistent in format, making automated processing difficult and error-prone. Extracting specific pieces of information, like a user ID or an error code, requires custom parsing logic that can break if the log message format changes. As applications scale and generate more logs, these inefficiencies become significant bottlenecks.

Structured logging directly addresses these issues:

Key Benefits of Adopting Structured Logs

  • Improved Searchability and Querying: With fields like user_id, transaction_id, or error_code explicitly defined, you can perform precise queries. Imagine instantly finding all logs for a specific customer experiencing an issue, or all occurrences of a particular error code across all your microservices. This drastically reduces the time spent sifting through irrelevant log lines.
  • Enhanced Performance and Efficiency: Log management systems can ingest, index, and analyze structured data much more efficiently than unstructured text. This means faster search results, lower processing overhead, and reduced storage costs as data can be more effectively compressed and managed.
  • Consistency Across Systems: In complex environments with multiple services, applications, and infrastructure components, having a consistent log structure is vital. It allows for centralized log aggregation and analysis, providing a unified view of your entire system’s behavior.
  • Facilitates Automation: Machine-readable logs are perfect for automation. You can build automated alerting based on specific log patterns or field values (e.g., alert if error_rate for payment_service exceeds a threshold). Structured logs also integrate seamlessly with CI/CD pipelines for automated quality gates or rollback triggers.
  • Better Analytics and Business Intelligence: Beyond troubleshooting, structured log data can be fed into analytics platforms to derive insights into user behavior, feature adoption, performance trends, and other business-relevant metrics.
  • Simplified Debugging and Troubleshooting: When an issue occurs, structured logs provide rich context. Instead of just an error message, you get associated metadata like request IDs, session IDs, and application versions, making it much easier to trace the root cause of a problem.

How to Implement Structured Logging

Transitioning to structured logging involves choosing a format, leveraging appropriate logging libraries, and integrating with log management tools.

Choosing a Format

JSON is the de facto standard for structured logs due to its simplicity, widespread library support across programming languages, and native compatibility with many log management systems. Its key-value pair structure is ideal for representing log event attributes.

Leveraging Logging Libraries

Most modern programming languages have robust logging libraries that support structured output or can be extended to do so.

  • Python Structured Logging: Python’s built-in logging module can be configured with custom formatters. Libraries like python-json-logger or structlog offer more direct support for JSON logging, allowing developers to easily add key-value pairs to their log messages.

  • Structured Logging Java: Libraries like Logback and Log4j2 are widely used in the Java ecosystem. They can be configured with JSON layouts (e.g., LogstashLogbackEncoder for Logback, or JSONLayout for Log4j2) to produce structured JSON logs. A common pattern is to use Mapped Diagnostic Context (MDC) to add contextual fields to all log messages within a certain scope, like a request.

  • C# Structured Logging: Serilog is a popular logging library for .NET that is built from the ground up with structured logging in mind. It makes it very easy to write rich, structured log events, automatically capturing message template parameters as distinct properties in the JSON output.

Integrating with Log Management Systems

The true power of structured logs is unlocked when they are sent to a log management system (like Netdata, Splunk, Elasticsearch/Kibana, etc.). These systems are designed to:

  1. Ingest logs from various sources.
  2. Parse the structured data (often automatically if it’s JSON).
  3. Index the fields for fast searching and querying.
  4. Provide visualization, alerting, and analysis capabilities.

The general flow is: an application generates a log event using a logging library configured for structured output. A log shipping agent (e.g., Fluentd, Vector, or Netdata agent) collects these logs and forwards them to the central log management system. The system then processes and indexes these structured logs, making them available for analysis.

Structured Logging Best Practices

To maximize the benefits of structured logging, consider these best practices:

  • Decide on a Consistent Log Format: Standardize on a single format (preferably JSON) across all your applications and services. This simplifies tooling and makes cross-service log correlation easier.
  • Use Standard Data Types for Fields: Employ consistent data types for common fields. For example, always use ISO 8601 format for timestamps (YYYY-MM-DDTHH:mm:ss.sssZ). Use consistent naming conventions for fields (e.g., camelCase or snake_case).
  • Include Essential Context and Metadata: Every log event should include:
    • A precise timestamp.
    • Log level (e.g., DEBUG, INFO, WARN, ERROR, CRITICAL).
    • Service/application name.
    • Hostname or container ID.
    • Correlation IDs (e.g., request ID, trace ID, session ID, user ID) to track operations across services.
    • Specific error codes or event types.
  • Keep Log Messages Concise but Informative: The message field should be human-readable, summarizing the event. Avoid excessive verbosity; detailed information should be in separate structured fields.
  • Log Semantically Meaningful Events: Think of logs as a stream of events with attributes. Instead of logging “User login failed: incorrect password”, log an event like UserLoginFailed with properties {"reason": "incorrect_password", "username": "..."}.
  • Do Not Log Sensitive Information: Avoid logging personally identifiable information (PII), passwords, API keys, or other sensitive data directly. If logging such data is unavoidable, ensure it’s properly masked, encrypted, or obfuscated, and that access to these logs is strictly controlled.
  • Consider All Stakeholders: Design your log structure to be useful for various teams: developers for debugging, SREs for operational monitoring, security teams for audits, and potentially product/business teams for analytics.
  • Regularly Monitor and Analyze Logs: Structured logs are a rich data source. Actively monitor them, set up alerts for critical conditions, and regularly analyze trends to proactively identify issues and opportunities for improvement.

Common Use Cases for Structured Logs

Structured logging supports a wide array of critical operational and analytical activities:

  • Debugging and Troubleshooting: Quickly filter logs by request_id to see the entire lifecycle of a failed request across multiple microservices, or search for all logs with a specific error_code.
  • Application Performance Monitoring (APM): Correlate structured logs with metrics and traces. For example, if a metric shows increased latency for an API endpoint, corresponding logs can provide details about slow database queries or external service calls.
  • Distributed Tracing: Enrich distributed traces with contextual log events. When a trace shows high latency in a particular service, the associated structured logs can reveal the exact operations and their parameters that contributed to the delay.
  • Security Auditing and Compliance: Track user actions, system access, and changes to critical configurations. Structured logs with fields like user_id, source_ip, action_performed, and resource_affected are invaluable for security audits, incident response, and meeting compliance requirements.
  • Business Intelligence and Analytics: Analyze patterns in user behavior, feature usage, conversion funnels, and system interactions. For instance, logs from an e-commerce platform can be analyzed to understand cart abandonment rates or the popularity of certain product categories.
  • Alerting and Anomaly Detection: Create highly specific alerts. Instead of alerting on a generic error message, you can alert if the count of payment_failed events with reason_code: "insufficient_funds" exceeds a certain threshold in a given time window.

Embracing structured logging fundamentally changes how you interact with and derive value from your log data. It shifts logs from being a passive record of past events to an active, queryable resource for understanding and improving your systems. By implementing a consistent log structure and leveraging the right tools, you can significantly enhance your observability, accelerate troubleshooting, and make more data-driven decisions.

Ready to take control of your logs? Explore how Netdata can help you harness the power of structured logging for comprehensive, real-time monitoring and troubleshooting across your entire stack. Visit Netdata’s website to learn more and get started.