The only agent that thinks for itself

Autonomous Monitoring with self-learning AI built-in, operating independently across your entire stack.

Metrics, Logs & Traces
Machine learning & MCP
5% of one CPU core, about 200 MB RAM
3GB disk, >1 year retention
2,000+ integrations, zero config
Dashboards, alerts out of the box
> Discover Netdata Agents

Centralized metrics streaming and storage

Aggregate metrics from multiple agents into centralized Parent nodes for unified monitoring across your infrastructure.

Stream from unlimited agents
Long-term data retention
High availability clustering
Data replication & backup
Scalable architecture
Enterprise-grade security
> Learn about Parents

Fully managed cloud platform

Access your monitoring data from anywhere with our SaaS platform. No infrastructure to manage, automatic updates, and global availability.

Zero infrastructure management
Metrics stay on your nodes
US-hosted metadata
Automatic updates & patches
Enterprise SSO & RBAC
SOC 2 Type 2 certified
> Explore Netdata Cloud

Deploy Netdata Cloud in your infrastructure

Run the full Netdata Cloud platform on-premises for complete data sovereignty and compliance with your security policies.

Complete data sovereignty
Air-gapped deployment
Custom compliance controls
Private network integration
Dedicated support team
Kubernetes & Docker support
> Learn about Cloud On-Premises

Powerful, intuitive monitoring interface

Modern, responsive UI built for real-time troubleshooting with customizable dashboards and advanced visualization capabilities.

Real-time chart updates
Customizable dashboards
Dark & light themes
Advanced filtering & search
Responsive on all devices
Collaboration features
> Explore Netdata UI

Monitor on the go

Native iOS and Android apps bring full monitoring capabilities to your mobile device with real-time alerts and notifications.

iOS & Android apps
Push notifications
Touch-optimized interface
Offline data access
Biometric authentication
Widget support
> Download apps

The future of infrastructure observability

See our strategic direction across AI-native observability, full-stack signals, operational intelligence, and enterprise platform maturity.

AI-native observability
Full-stack signal coverage
Operational intelligence
Enterprise platform maturity
Agent releases every 6 weeks
Cloud continuous delivery
> Explore Product Roadmap

Best energy efficiency

True real-time per-second

100% automated zero config

Centralized observability

Multi-year retention

High availability built-in

Zero maintenance

Always up-to-date

Enterprise security

Complete data control

Air-gap ready

Compliance certified

Millisecond responsiveness

Infinite zoom & pan

Works on any device

Native performance

Instant alerts

Monitor anywhere

AI-native observability

Continuous delivery

Open source foundation

80% Faster Incident Resolution

AI-powered troubleshooting from detection, to root cause and blast radius identification, to reporting.

True Real-Time and Simple, even at Scale

Linearly and infinitely scalable full-stack observability, that can be deployed even mid-crisis.

90% Cost Reduction, Full Fidelity

Instead of centralizing the data, Netdata distributes the code, eliminating pipelines and complexity.

See and Map Your Entire Network

Live topology, flow analytics, and SNMP device and trap monitoring — unified with your full-stack observability.

Single Pane of Glass

Eliminate SSH access for monitoring and troubleshooting systems and applications.

Control Without Surrender

SOC 2 Type 2 certified with every metric kept on your infrastructure.

Integrations

2,000+ collectors and notification channels, auto-discovered and ready out of the box.

2,000+ data collectors
Auto-discovery & zero config
Cloud, infra, app protocols
Notifications out of the box
> Explore integrations
Real Results
46% Cost Reduction

Reduced monitoring costs by 46% while cutting staff overhead by 67%.

— Leonardo Antunez, Codyas

Zero Pipeline

No data shipping. No central storage costs. Query at the edge.

From Our Users
"Out-of-the-Box"

So many out-of-the-box features! I mostly don't have to develop anything.

— Simon Beginn, LANCOM Systems

No Query Language

Point-and-click troubleshooting. No PromQL, no LogQL, no learning curve.

Enterprise Ready
67% Less Staff, 46% Cost Cut

Enterprise efficiency without enterprise complexity—real ROI from day one.

— Leonardo Antunez, Codyas

SOC 2 Type 2 Certified

Zero data egress. Only metadata reaches the cloud. Your metrics stay on your infrastructure.

Full Coverage
2,000+ Collectors

Auto-discovered and configured. No manual setup required.

Any Notification Channel

Slack, PagerDuty, Teams, email, webhooks—all built-in.

Built for the People Who Get Paged

Because 3am alerts deserve instant answers, not hour-long hunts.

Every Industry Has Rules. We Master Them.

See how healthcare, finance, and government teams cut monitoring costs 90% while staying audit-ready.

Monitor Any Technology. Configure Nothing.

Install the agent. It already knows your stack.
From Our Users
"A Rare Unicorn"

Netdata gives more than you invest in it. A rare unicorn that obeys the Pareto rule.

— Eduard Porquet Mateu, TMB Barcelona

99% Downtime Reduction

Reduced website downtime by 99% and cloud bill by 30% using Netdata alerts.

— Falkland Islands Government

Real Savings
30% Cloud Cost Reduction

Optimized resource allocation based on Netdata alerts cut cloud spending by 30%.

— Falkland Islands Government

46% Cost Cut

Reduced monitoring staff by 67% while cutting operational costs by 46%.

— Codyas

Real Coverage
"Plugin for Everything"

Netdata has agent capacity or a plugin for everything, including Windows and Kubernetes.

— Eduard Porquet Mateu, TMB Barcelona

"Out-of-the-Box"

So many out-of-the-box features! I mostly don't have to develop anything.

— Simon Beginn, LANCOM Systems

Real Speed
Troubleshooting in 30 Seconds

From 2-3 minutes to 30 seconds—instant visibility into any node issue.

— Matthew Artist, Nodecraft

20% Downtime Reduction

20% less downtime and 40% budget optimization from out-of-the-box monitoring.

— Simon Beginn, LANCOM Systems

Pay per Node. Predictable Pricing.

Pay per node, with unlimited metrics and generous log and trace quotas.

Free tier—forever
No metric limits or caps
Retention you control
Cancel anytime
> See pricing plans

What's Your Monitoring Really Costing You?

Most teams overpay by 40-60%. Let's find out why.

Expose hidden metric charges
Calculate tool consolidation
Customers report 30-67% savings
Results in under 60 seconds
> See what you're really paying

Your Infrastructure Is Unique. Let's Talk.

Because monitoring 10 nodes is different from monitoring 10,000.

On-prem & air-gapped deployment
Volume pricing & agreements
Architecture review for your scale
Compliance & security support
> Start a conversation

Monitoring That Sells Itself

Deploy in minutes. Impress clients in hours. Earn recurring revenue for years.

30-second live demos close deals
Zero config = zero support burden
Competitive margins & deal protection
Response in 48 hours
> Apply to partner

Per-Second Metrics at Homelab Prices

Same engine, same dashboards, same ML. Just priced for tinkerers.

Community: Free forever · 5 nodes
Homelab: $90/yr · personal, non-commercial use
> Get the Homelab Plan

$1,000 Per Referral. Unlimited Referrals.

Your colleagues get 10% off. You get 10% commission. Everyone wins.

10% of subscriptions, up to $1,000 each
Track earnings inside Netdata Cloud
PayPal/Venmo payouts in 3-4 weeks
No caps, no complexity
> Get your referral link
Cost Proof
40% Budget Optimization

"Netdata's significant positive impact" — LANCOM Systems

Calculate Your Savings

Compare vs Datadog, Grafana, Dynatrace

Savings Proof
46% Cost Reduction

"Cut costs by 46%, staff by 67%" — Codyas

30% Cloud Bill Savings

"Reduced cloud bill by 30%" — Falkland Islands Gov

Enterprise Proof
"Better Than Combined Alternatives"

"Better observability with Netdata than combining other tools." — TMB Barcelona

Real Engineers, <24h Response

DPA, SLAs, on-prem, volume pricing

Why Partners Win
Demo Live Infrastructure

One-line install, real data—no sandbox needed

Zero Tickets, High Margins

Auto-config + per-node pricing = predictable profit

Homelab Ready
Free Video Course

8-episode Netdata tutorial by LearnLinux.tv

80k+ GitHub Stars

Open source, 690+ contributors

Worth Recommending
Product That Delivers

Customers report 90% cost cuts, 99% downtime reduction

Zero Risk to Your Rep

Free tier lets them try before they buy

AI Support Assistant, Available 24/7

Nedi has access to all official documentation, source code, and resources. Ask any question about Netdata—responds in your language.

Deployment & configuration
Troubleshooting & sizing
Alerts & notifications
Evidence-based answers
> Ask Nedi now

Never Fight Fires Alone

Docs, community, and expert help—pick your path to resolution.

Learn.netdata.cloud docs
Discord, Forums, GitHub
Premium support available
> Get answers now

60 Seconds to First Dashboard

One command to install. Zero config. 2,000+ integrations documented.

Linux, Windows, K8s, Docker
Auto-discovers your stack
> Read our documentation

80,000+ Engineers Strong

690+ contributors. 1.5M daily downloads. One mission: simplify observability.

Per-Second. 90% Cheaper. Data Stays Home.

Side-by-side comparisons: costs, real-time granularity, and data sovereignty for every major tool.

See why teams switch from Datadog, Prometheus, Grafana, and more.

> Browse all comparisons
Edge-Native Observability, Born Open Source
Per-second visibility, ML on every metric, and data that never leaves your infrastructure.
Founded in 2016
690+ contributors worldwide
Remote-first, engineering-driven
Open source first
> Read our story
Promises We Publish—and Prove
12 principles backed by open code, independent validation, and measurable outcomes.
Open source, peer-reviewed
Zero config, instant value
Data sovereignty by design
Aligned pricing, no surprises
> See all 12 principles
Edge-Native, AI-Ready, 100% Open
81.4k+ stars. Full ML, AI, and automation—GPLv3+, not premium add-ons.
81.4k+ GitHub stars
GPLv3+ licensed forever
ML on every metric, included
Zero vendor lock-in
> Explore our open source
Build Real-Time Observability for the World
Remote-first team shipping per-second monitoring with ML on every metric.
Remote-first, fully distributed
Open source (81.4k+ stars)
Challenging technical problems
Your code on millions of systems
> See open roles
Meet the Team Behind Netdata
Conferences, meetups, and tradeshows where you can see Netdata in action and talk to the engineers who build it.
Live demos and deep dives
Book 1-on-1 meetings
Talks and panel sessions
Event recaps and photos
> See all events
Talk to a Netdata Human in <24 Hours
Sales, partnerships, press, or professional services—real engineers, fast answers.
Discuss your observability needs
Pricing and volume discounts
Partnership opportunities
Media and press inquiries
> Book a conversation
Your Data. Your Rules.
On-prem data, cloud control plane, transparent terms.
Trust & Scale
80,000+ GitHub Stars

One of the most popular open-source monitoring projects

SOC 2 Type 2 Certified

Enterprise-grade security and compliance

Data Sovereignty

Your metrics stay on your infrastructure

Validated
University of Amsterdam

"Most energy-efficient monitoring solution" — ICSOC 2023, peer-reviewed

ADASTEC (Autonomous Driving)

"Doesn't miss alerts—mission-critical trust for safety software"

Community Stats
690+ Contributors

Global community improving monitoring for everyone

1.5M+ Downloads/Day

Trusted by teams worldwide

GPLv3+ Licensed

Free forever, fully open source agent

Why Join?
Remote-First

Work from anywhere, async-friendly culture

Impact at Scale

Your work helps millions of systems

AI SRE comparison Reviewed Nov 2026

Netdata vs Traversal

Traversal reasons over the observability tools you already pay for, so its answers inherit their sampling, retention and blind spots, and its confidence drops when visibility or traces are missing. Netdata AI investigates from data Netdata collects itself: every metric every second, scored by machine learning as it arrives and ranked for the incident before the AI starts. The root cause of any alert is one click away.

Open source 81.4k+ GitHub stars

Netdata AI root cause analysis report for an alert, with timeline, affected systems and findings

One product, the full stack

  • Metrics
  • Logs
  • Traces and service maps
  • RUM and synthetic journeys
  • Network topology and flows
  • 50+ databases
  • Cloud and Kubernetes
  • AI troubleshooting
integrations
2,000+
stock alerts
1,100+
system metric resolution
1 s
GitHub stars
81.4k+

Netdata and Traversal at a glance

What the AI investigates from

Netdata

Per-second metrics, logs and traces Netdata holds, scored by ML as they are collected.

Traversal

Your existing observability tools, read through integrations and re-indexed.1

Starting an investigation

Netdata

One click on any alert, any time window or question; also on a schedule.

Traversal

A question with a start time and timezone; Workers watch alert channels.459

When evidence is missing

Netdata

Every sample kept per second, every span stored, every log field indexed.

Traversal

Rates a theory Medium confidence when visibility or traces are missing.4

Where it runs

Netdata

Data on your Agents and Parents; Cloud as SaaS or On-Prem, air-gapped included.

Traversal

SaaS, single-tenant SaaS, or BYOC run by Traversal in your cloud account.2

How the AI is priced

Netdata

Per investigation or an annual bundle; conversations included on Business.

Traversal

Credits per investigation, with limits for people, automation and Workers.6

Numbers in Traversal text refer to the sources at the end of this page, reviewed Nov 2026.
Answers you can trust, because nothing was sampled away

Where Traversal fits

Traversal is an AI SRE built for large enterprises that already run heavy observability stacks. It reads tools such as Datadog, Dynatrace, Grafana, Prometheus, Splunk and Elasticsearch, along with code, Kubernetes, tickets and chat, maps entities and relationships into what it calls a Production World Model, and runs causal searches across that data to return a root cause with a confidence level, cited evidence and a timeline. Workers can sit in alert and incident channels and work on their own. Traversal’s own materials say it requires existing observability instrumentation and is designed for enterprise-scale environments: it reasons over your observability stack rather than replacing it.

Using both

Already running Traversal? Put Netdata underneath it. Traversal connects any MCP server over Streamable HTTP or SSE, and Netdata Cloud runs one with fleet-wide access, so Traversal’s investigations can call Netdata’s per-second metrics, anomaly rankings, correlated metrics, alerts and live views of processes and connections. Teams get Netdata’s evidence inside the AI SRE they already use.

Day to day with Traversal and with Netdata

The Traversal side comes from Traversal’s own documentation; the Netdata side from the Netdata product description.

Asking the right question

With Traversal

Investigations look mainly backwards from the time you give. Traversal’s tips name a wrong or missing time as a common cause of vague, low-confidence results, and ask for trace IDs, service names, error strings and deployment versions.

With Netdata

An alert carries its own seconds, so one click starts from the right window. Netdata also finds interesting windows on its own, by looking for the moments when anomalies clustered across the stack.

When the data was never kept

With Traversal

Traversal reads the tools you already run, so an investigation inherits their sampling, retention and resolution, and its confidence levels drop when visibility or traces are missing.

With Netdata

Every metric is kept per second with its anomaly flag, every received span is stored and every log field is indexed, on your own infrastructure, so the detail an incident needs was collected before anyone asked.

Getting data to the AI

With Traversal

A Connector reaches private sources, and a Processor ingests and indexes logs to reduce egress; both are services your team deploys and manages, with Helm on Kubernetes or as containers.

With Netdata

One Agent per node collects, stores and scores its own data, with 2,000+ integrations discovered automatically. Parents scale the same setup horizontally to fleets of 100,000+ nodes.

Putting AI on the alert stream

With Traversal

Alert Workers give each alert in a channel a verdict and their reasoning, and Incident Workers join incident channels and work them through recovery.

With Netdata

Every alert opens into its root cause one click away, with 1,100+ stock alerts already watching each instance. Teams that want investigations running on their own can talk to us about AI SRE.

Budgeting AI work

With Traversal

Every investigation consumes credits, with separate limits for investigations people start, automated triggers and each Worker; follow-ups are not metered again.

With Netdata

No second observability bill underneath: the stack is priced per node, AI Conversations are included on the Business plan, subject to fair use, and AI Investigations are bought per investigation or as an annual bundle.

Traversal features come from its documentation, checked on the date shown in Sources.

Where Netdata is different

01

The cause is ranked before the AI starts

Netdata AI does not start by searching other tools; it starts from what Netdata already scored.

  • Every metric learned. 18 machine learning models per metric, trained where the data lives, flag a sample only when all of them agree, which removes about 99% of false positives.
  • Ranked for the incident. Anomaly Advisor ranks the metrics that were anomalous or changed most in the window, across systems, networks and applications; the root cause is usually among the top 30–50.
  • Dependencies from behavior. Components that keep turning anomalous together reveal how they depend on each other, with no service definitions to write.
  • A report in about two minutes. AI Investigations reason over that evidence, from any alert, time window or question, on demand or on a schedule.

The result: 80% faster MTTR, with no time window or trace ID to supply first. Malmö stad cut a full day of troubleshooting to under 30 minutes (case study).

Netdata Anomaly Advisor ranking the metrics that were anomalous in an incident window

02

No blind spots for the AI to reason around

An AI that reads other tools can only be as complete as they are. Netdata collects everything, every second.

  • Per-second detail. System metrics are collected every second and kept at that resolution for 14 days by default, with per-minute and per-hour tiers for months and years.
  • Every span, every field. OpenTelemetry traces are stored and indexed on your Agents, and logs keep every field indexed at about 1/4 of their raw size.
  • The whole stack. Infrastructure, Kubernetes, 50+ databases, network devices, topology and flows, cloud services, RUM and synthetic journeys share one timeline.
  • Gaps shown as gaps. When a sample is late or a node does not answer, the chart says so, so a partial answer is never presented as complete.
Netdata trace waterfall of a checkout request, 160 spans across 12 services

03

Your observability data stays on your infrastructure, open to any AI

Netdata distributes the code, instead of centralizing the data, and nothing is re-indexed into someone else’s platform.

  • Data at the edge. Metric samples, logs, traces and flow records stay on your Agents and Parents; Netdata Cloud stores metadata and runs On-Prem, including air-gapped.
  • MCP on every node. Every Agent, Parent and Netdata Cloud runs an MCP server, so Claude Code, Cursor, ChatGPT or any MCP client reads the evidence itself: per-second metrics, anomaly rankings, live processes and connections.
  • Your context included. MCP Connections let Netdata AI combine monitoring data with GitHub, Atlassian (Jira, Confluence, Bitbucket) and PagerDuty.
  • Enterprise controls. SOC 2 Type 2 certified, with SSO, SCIM, room-scoped roles and a sensitive-data permission.
Netdata AI troubleshooting overlay where an engineer asks a question about the infrastructure

How each one gets to the root cause

Netdata and Traversal compared by capability
CapabilityNetdataTraversal
Observability dataFull-stack data, built inInfrastructure, Kubernetes, 50+ databases, logs, OpenTelemetry traces, network devices, topology and flows, RUM and synthetic journeys, collected and stored by Netdata itself.Needs an observability stackReads Datadog, Dynatrace, Grafana, Prometheus, Loki, Tempo, Splunk, Elasticsearch, CloudWatch and others; its Processor ingests logs only.3711
Anomaly detectionML on every metric18 unsupervised models per metric, with the anomaly flag stored with every sample, so anomaly rates exist for any metric, window and history.Baselines mined from your toolsStatistical baselines and relationships mined from the telemetry and code it can read.1
Finding the causeRanked evidence, then AIAnomaly Advisor and Metric Correlations rank what was anomalous or changed most; Netdata AI reasons over those few hundred metrics, with logs, traces and live views.Causal search over re-indexed dataRe-indexes telemetry for parallel queries and returns a root cause with a High, Medium or Low confidence level, cited evidence, a timeline and next steps.14
Service dependenciesLearned from behavior and connectionsDependencies found from anomalies that cluster together, a map of processes, containers and services from live network connections, and a service map from traces.A model built from your toolsA Production World Model of entities and relationships, built by mining the telemetry and code Traversal is connected to.1
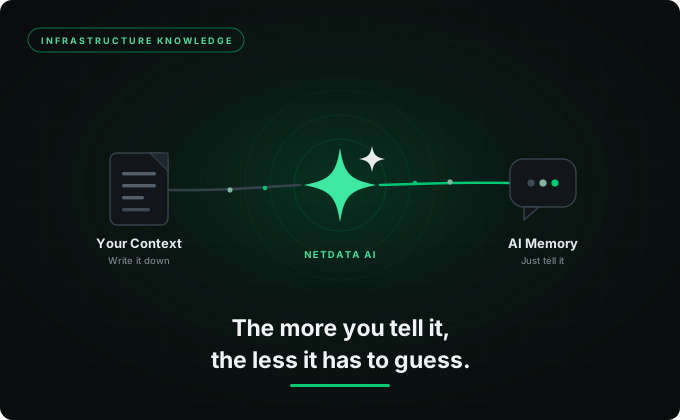
Team knowledgeMeaning collected with the dataEvery metric arrives with its unit, family and aggregation; Infrastructure Knowledge and AI Memory, generated from the infrastructure or written, ground the AI further.Runbooks and standing instructionsKnowledge Bank of runbooks, documents and tribal knowledge, plus standing instructions per investigation, channel or Worker.10
Components to runAgents that run themselvesOne Agent per node, Parents as needed; storage, machine learning and alerting are built in, and Agents update on their own.Connector and Processor to manageAn optional Connector for private sources and a Processor for log ingestion and redaction, deployed and managed by your team.23
Data residencyStays on your Agents and ParentsMetric samples, logs, traces and flow records stored on your infrastructure; Netdata Cloud stores metadata only, SaaS or On-Prem.Indexed into Traversal’s platformProcessors index log data into the Traversal platform; BYOC places Traversal’s data stores in your cloud account, operated by Traversal.23
Actions and contextCode, tickets and incidents in contextMCP Connections bring GitHub, Atlassian (Jira, Confluence, Bitbucket), PagerDuty and custom MCP servers into Netdata AI investigations.Read-only unless grantedReads your systems unless you grant write access, for example a token with write scope or an MCP tool that changes state.28
AI assistant accessMCP servers on every nodeMCP servers on every Agent, Parent and Netdata Cloud, with live Functions for processes, connections, logs, traces, topology and flows, under the user’s role.Quick mode over MCPTraversal MCP for Claude, Cursor and ChatGPT; investigations called over MCP run in the quick lightning mode.4

Numbers in Traversal cells refer to the sources at the end of this page.

Trusted by teams worldwide
TencentLinkedInNVIDIAIntelSiemensTeslaVolvo CarsShopifyCoinbaseTelefónicaPwCAkamaiDatabricksCanvaEsriIONOS
Ever since Netdata included AI insights, I can now use Netdata to troubleshoot really difficult issues, and even detect and find attacks, memory leaks and so on.
Johnnie Midelf IT-Specialist, Malmö stad

Frequently asked questions

Sources

Reviewed Nov 2026

  1. Traversal documentation: About Traversal, checked 2026-11-21
  2. Traversal documentation: Deployment options, checked 2026-11-21
  3. Traversal documentation: Traversal Processor, checked 2026-11-21
  4. Traversal documentation: Investigations, checked 2026-11-21
  5. Traversal documentation: Tips, checked 2026-11-21
  6. Traversal documentation: Usage limits, checked 2026-11-21
  7. Traversal documentation: Integrations, checked 2026-11-21
  8. Traversal documentation: MCP servers, checked 2026-11-21
  9. Traversal documentation: Workers and Alert Workers, checked 2026-11-21
  10. Traversal documentation: Knowledge Bank and Customization, checked 2026-11-21
  11. Traversal: AI info page (stated limitations), checked 2026-11-21

Claims about Traversal come from its official documentation, checked on the dates shown.